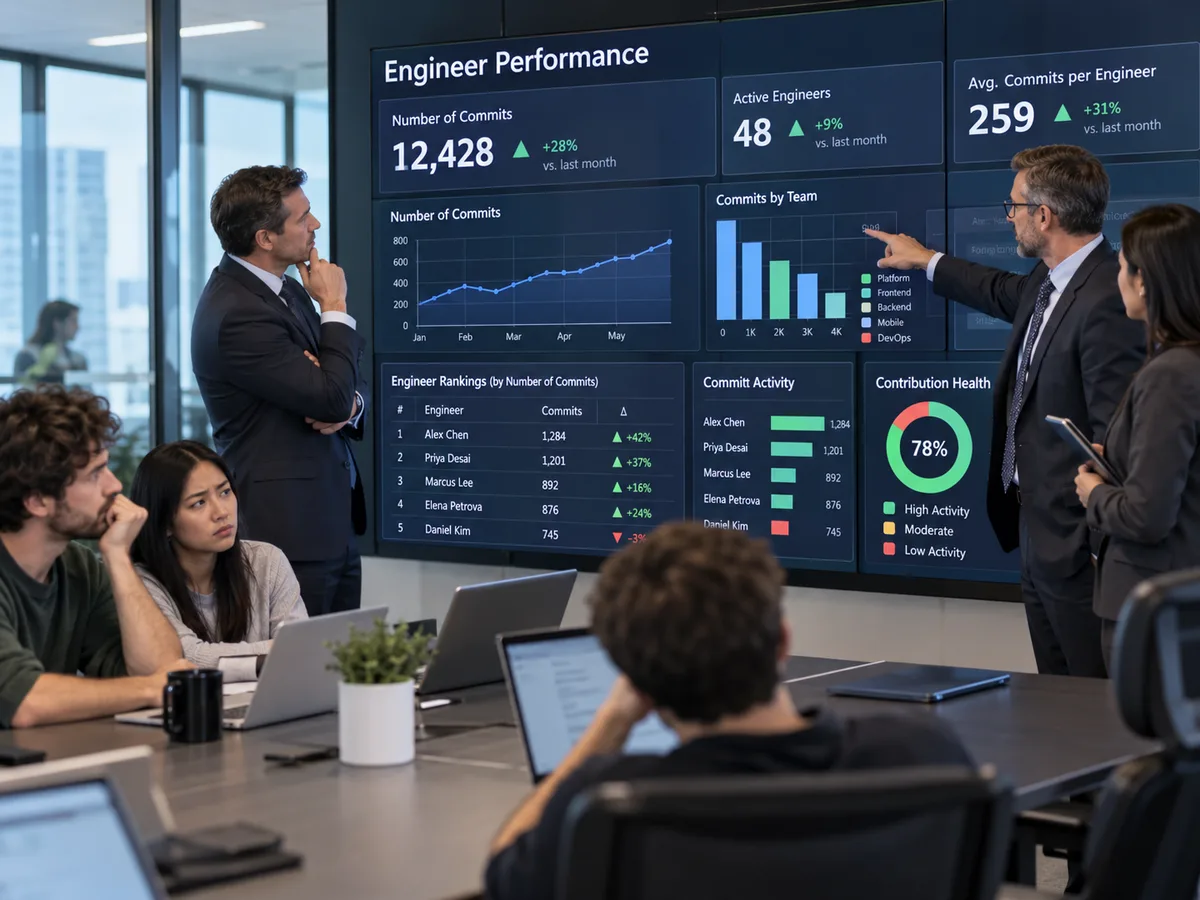
In 2025 my employer measured commits. A KPI dashboard counted them per person, and one day I got a warning: my number was lower than some other people’s, and I was expected to bring it up.
At the time I was the lead architect, the technical decision maker, a mentor, a senior software engineer, and the team lead. Five roles, and only one of them is mostly measured in code that I personally push. Being judged on raw commit count in that position felt wrong to me then. Looking back, I can say more precisely why.
What happened
The facts are short. A dashboard counted commits per person. My number sat below some of my colleagues’ numbers. Someone noticed the gap, I got scolded for it, and the expected remedy was more commits.
Nothing in that chain asked what the commits contained, what the other people’s roles were, or what I was doing with the hours that did not end in a commit. The number was treated as the performance, not as a signal about it.
Why commit count fails as a KPI
The oldest objection has a name. Goodhart’s law is usually quoted in Marilyn Strathern’s phrasing: when a measure becomes a target, it ceases to be a good measure. Campbell’s law says the same thing about social indicators with sharper teeth: the more a quantitative indicator is used for decision-making, the more it is subject to corruption pressures, and the more it distorts the process it was meant to monitor. Telling a person their number is too low is already a decision driven by the indicator.
And commits are unusually easy to corrupt, because a commit has no fixed size. It can be a one-character typo fix or a three-thousand-line migration. Anyone can double their count tomorrow by splitting the same work into smaller pieces, and the dashboard will report it as improvement. Nothing about the software changes. The number moves because the person learned what the number rewards.
It also pairs badly with good practice. Plenty of teams squash-merge pull requests, so a branch with twenty commits lands on the main branch as one. Depending on where the dashboard counts, a disciplined workflow can make an engineer look less productive than someone who pushes every intermediate save straight to a shared branch.
The work that never becomes a commit
The bigger problem is what the count cannot see. A large part of a lead’s job leaves no trace in git log:
- Architecture and design reviews: deciding how a system is shaped before anyone writes it.
- Code review: reading, questioning, and improving other people’s changes, which shows up under their name.
- Mentoring: time spent making someone else faster, which also shows up under their name.
- Unblocking: answering the question that has stalled a teammate for a day.
- Decisions that prevent code: talking the team out of a service, a rewrite, or a feature nobody needs. The best outcome of that work is code that never exists, and it counts as zero.
- Incident work: diagnosing a production problem often ends in a small fix, or in a config change outside the repository entirely.
This is force-multiplier work. Its output is measured in other people’s throughput and in the problems the team does not have. A metric that counts only personal commits punishes exactly that work and rewards whatever produces the most commits, which is often noise.
Comparing different jobs with one number
Putting a lead architect’s commit count next to individual contributors’ counts is a category error. The roles are designed to spend time differently. If the team lead commits as often as the most active contributor, one of two things is true: the leadership work is not getting done, or the count is being padded. Neither is what the organization wants, and the dashboard cannot tell them apart.
How I met the target
I did not change how I worked. I changed how the work reached the repository.
My habit had always been to commit my work as a whole when I had the time: finish a piece, review it myself, commit it in one go, and get back to the design reviews and the people waiting on me. That habit is exactly what the dashboard read as low output.
So I wrote an agent skill and called it crazy-commiting. Its job was narrow. It took all of my pending changes and split them into the maximum number of reasonable commits. Not noise and not whitespace churn: every commit still had to be a coherent, self-contained step with an honest message, the kind a reviewer could read on its own. It simply refused to put two things in one commit when they could stand as two. From then on my workflow changed by exactly one step. Instead of committing my code myself, I opened an agent prompt, typed “do the crazy commiting”, and left it to do its work.
The code was the same code. The hours were the same hours. The only thing that grew was the number of entries in git log, and with it my bar on the dashboard.
A few weeks later management was very happy. My numbers had gone up, and they genuinely believed my performance had improved. As far as the dashboard could tell, it had. That is the whole point of this post in one sentence: the metric could not distinguish between an engineer who got better and an engineer who got better at feeding the metric, and the people reading it took the second for the first.
What the research actually recommends
This is not a new problem, and the industry research does not support it. The DORA program, the research behind the book Accelerate by Nicole Forsgren, Jez Humble, and Gene Kim, measures software delivery performance with four key metrics: deployment frequency, lead time for changes, change failure rate, and time to restore service (recently renamed failed deployment recovery time). They describe how a team’s delivery system behaves, and they are designed to measure teams and systems, not to rank the individuals inside them.
The SPACE framework (Forsgren, Storey, Maddila, Zimmermann, Houck, and Butler, 2021) goes further. It splits developer productivity into five dimensions: satisfaction and well-being, performance, activity, communication and collaboration, and efficiency and flow. Commit count is an activity metric, and the authors explicitly caution against judging productivity on activity alone. They recommend looking across several dimensions at once, so that one number cannot stand in for the whole picture.
Neither framework is a scoreboard for people. Both are tools for understanding a system.
What a healthy alternative looks like
The fix isn’t a better counter. It’s goals tied to outcomes and roles.
- Outcome-based goals: the migration shipped, the incident rate dropped, the new hire is productive on their own, the architecture decision held up under load. These are things a manager and an engineer can agree on up front and check honestly later.
- Role-appropriate expectations: a lead is evaluated on the team’s delivery, the quality of technical decisions, and the growth of the people around them. An individual contributor is evaluated closer to their own output. Writing that down per role removes the temptation to compare everyone on one axis.
- Metrics as conversation starters: a low commit count can be a fine prompt for a question. “Where is your time going?” has a useful answer. The mistake is skipping the question and treating the number as the verdict.
Activity data is not useless. It is context. The moment it becomes the conclusion instead of the start of a conversation, it stops describing the work and starts shaping it.
Why this is an antipattern
Using individual commit count as a performance KPI, and reprimanding people when their number falls behind, is an antipattern because the intent is reasonable and the incentive is backwards. The intent is to find out who is contributing. What it actually rewards is splitting work into more commits, which I proved by handing that job to an agent skill and watching my perceived performance rise while the work stayed exactly the same. It also rewards pushing noise, and avoiding the reviews, mentoring, design work, and preventive decisions that never land under your own name. The damage falls hardest on the people whose job is to make others effective: the leads and architects learn that multiplying the team counts for nothing, the dashboard fills with inflated numbers that look like progress, and the organization ends up measuring how often people commit instead of whether the software and the team are getting better.
More on what I build and how I work lives at lezli01.is-a.dev.